

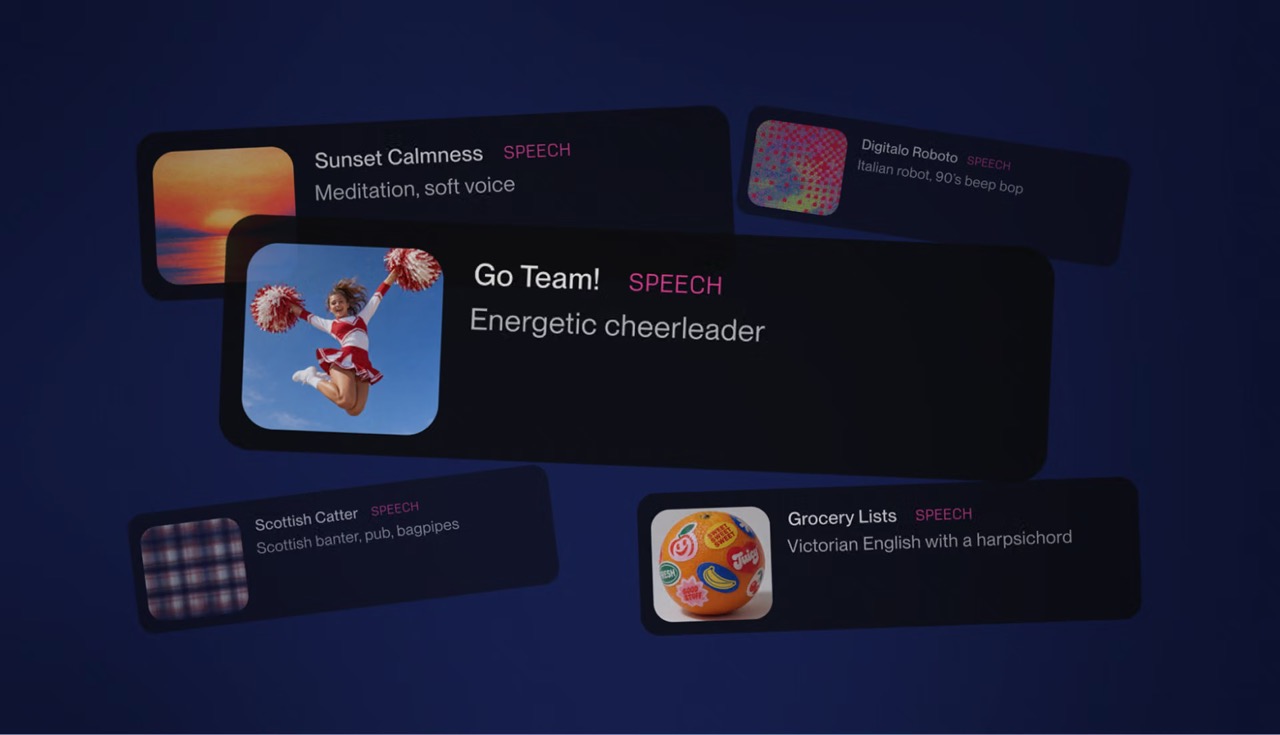
Suno launched Speech (beta) on Oct. 1. It is the company's first product beyond song generation. The model creates spoken voice and original background music together as a single track. Users type an idea, a poem or their own writing, then describe the voice and musical style they want. The music can be switched off for voice-only output. An advanced mode lets users supply a full script and set voice gender, delivery style and how much each generation varies.
The beta is open to all users on web and mobile after a month of testing with a small group. It runs on Suno's existing credit plans, with no separate pricing and no API announced. Suno is open about the rough edges: accents drift, and dramatic pauses can run long.
CEO Mikey Shulman discussed the launch the same day at Bloomberg Screentime. He said Suno wants to be a destination for creative entertainment beyond music. He also said the company is now "far beyond" its last reported figures of two million subscribers and $300 million in revenue. Speech is a return to Suno's roots: its first public release, in 2023, was Bark, an open-source text-to-speech model.
Speech arrives three weeks after Suno launched its v6 models. While ElevenLabs has gone from voice to song generation with ElevenMusic, Suno's Speech product now takes the platform into ElevenLabs' home turf of voice generation. The announcement doesn't say how Speech's voices were built or what stops users from imitating real people. Asked about labeling AI music at Screentime, Shulman said it's good that firm rules don't exist yet. Voice is where that answer will be tested hardest.